Neural networks are circuits, too
Writing neural-network weights becomes less mysterious when we remember that neural networks are circuits. We explore this connection through experiments with executable programs, arithmetic and cryptographic hashes.
A recent MIT post, Sparks of Weight-Space Programming, showed that language models can read, write and modify neural networks directly through their weights. The experiments included identifying what trained networks do, repairing a failing network and writing new game-playing networks. The results attracted a lot of attention, and understandably so.
But should we be that surprised?
We tend to treat neural networks as a fundamentally different kind of computation from traditional software. We usually train them rather than program them, and their weights can seem fundamentally different from instructions in an executable.
But neural networks are circuits. We can use neurons to implement logic gates, combine those gates into larger computations, and construct networks that perform arithmetic, hashing and other familiar operations. With memory and control flow, circuits also form the basis of general-purpose computers.
Seen this way, neural-network weights are another way of representing a computation. And language models already work across different representations, from source code to executable bytes and other file formats.
This doesn’t mean that reading or writing neural-network weights is easy. Knowing that two representations can express the same computation doesn’t tell us whether a language model can translate between them correctly. That’s what makes these results interesting.
We explored this connection through a series of experiments using Astra, the same model used in the MIT paper. The examples range from generating executable files directly to expressing arithmetic, compiled programs and cryptographic hashes as neural-network circuits.
How well can a language model actually translate between these representations, and how far can it go?
Writing executable files directly
Let’s start with something that isn’t a neural network at all. When we ask a language model to write software, we usually expect source code. A compiler turns that code into an executable, or an interpreter runs it. But what if the model skips the source code and writes the executable itself?
We asked Astra to generate a little Mario-style game directly as executable bytes. The model supplied machine instructions, graphics and game logic as hexadecimal characters, which we decoded into a 3,840-byte DOS file. The playable version includes one correction after feedback.
A game, written as bytes
Interactive example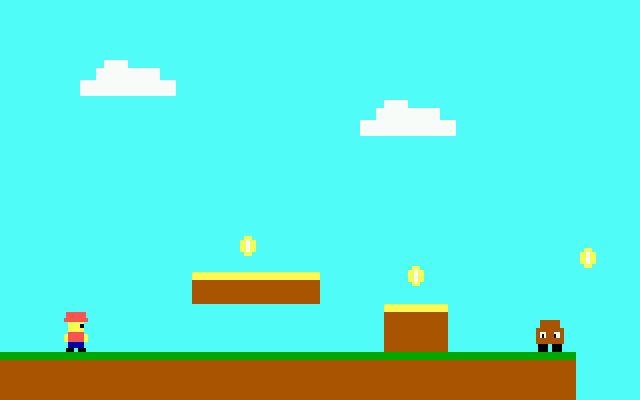
Arrow keys to move, Space to jump. Touch controls are included. Original Mario-style game generated as a DOS executable, with one feedback-assisted correction. Runs in DOSBox via js-dos.
Once you press Play, the model has no further involvement. The emulator simply executes the generated file. Movement, gravity, collisions and the game’s other behaviours follow the instructions in those bytes.
Most of us would write source code and let a compiler produce the executable. Here, the model supplied the final representation directly. The distinction matters because the model isn’t being asked to describe how a program should work. It’s being asked to produce the bytes that make it work.
And executables aren’t the only format it can work with. We also asked the model to generate files directly in several other formats, including SVG, JPEG, animation and MIDI. The model emitted the file contents themselves, including compressed image bytes and the notes and timing of a MIDI arrangement. We saved those outputs in the appropriate formats, without an intermediate program generating the files.
The model wrote the file itself
Interactive exampleThe model emitted the file contents directly. It didn’t write a program to generate them. The viewer, MIDI player or emulator interprets those bytes.
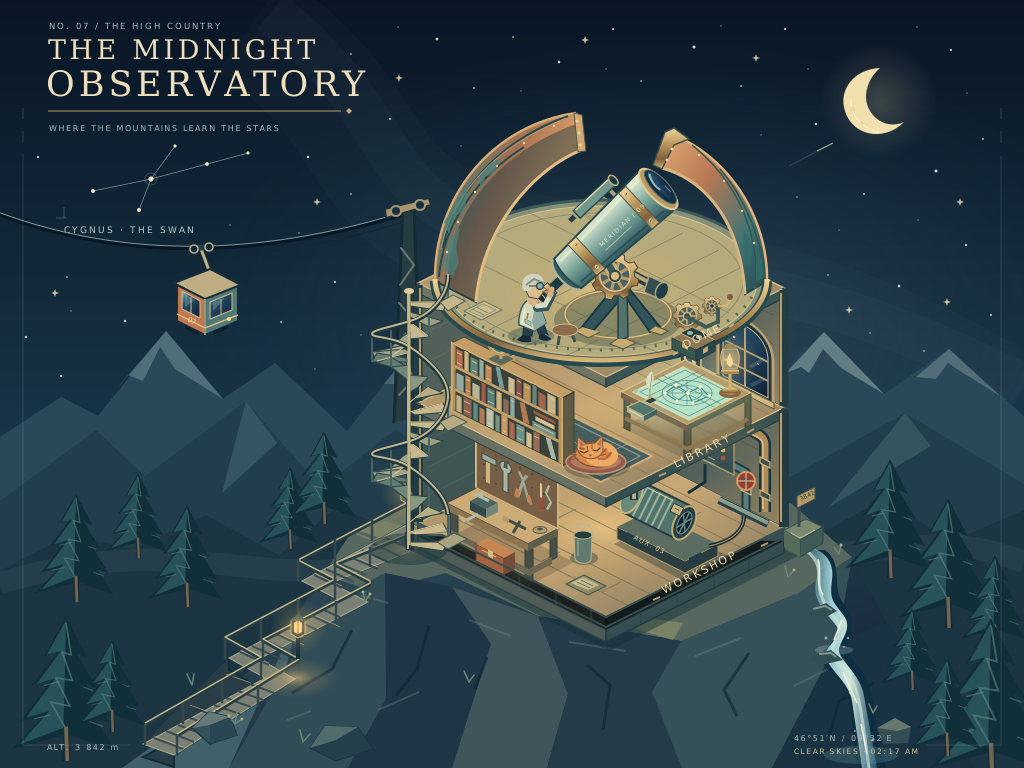
Shapes, colours, coordinates and text become a drawing when a browser interprets them. This file contains 743 elements.
Look at the file bytes
Loading the original experiment…
First 192 bytes of the same file, re-encoded here for inspection. Changing this display is not another model attempt.
Some formats are easier than others. The SVG example is a detailed illustration of an observatory, described through shapes, coordinates, colours and text. A browser interprets those instructions to produce the drawing.
The JPEG is a useful counterexample. Its structure is valid, but the apple it depicts is crude. Unlike SVG, where recognisable shapes can be specified explicitly, JPEG requires the model to encode appearance through compressed coefficients and tables. Producing a file that opens correctly doesn’t necessarily mean producing the right contents.
These examples show that a language model can sometimes generate a file directly in the format another program reads, even when that format is far removed from ordinary human-readable instructions. So why should neural-network weights be fundamentally different?
From neurons to logic circuits
A neural network consists of operations connected together. By choosing the right weights and biases, we can make those operations implement logic gates.
Take a ReLU neuron. It computes a weighted sum of its inputs, adds a bias, and replaces negative results with zero. For binary inputs A and B, consider:
h = ReLU(A + B − 1)
The result is one only when both inputs are one. We’ve constructed an AND gate. Add another neuron:
out = ReLU(1 − h)
Now the output is zero when both inputs are one, and one otherwise. That’s a NAND gate.
There is no training involved. We simply choose weights that implement the logic we want, and we can check the result for all four possible input combinations.
NAND is particularly useful because NAND gates can be combined to implement any finite Boolean circuit. That includes arithmetic, comparisons, conditional decisions and the logic used to update stored state. A fixed feed-forward neural network expresses a bounded computation; a general-purpose computer additionally retains state and repeats operations through its control flow.
So there’s nothing mysterious, in principle, about constructing a neural network that behaves like a conventional program. The harder question is whether a language model can construct the correct network for a more complicated computation.
A calculator made of 123 neurons
We asked Astra to produce a neural network implementing a calculator. It takes two eight-bit numbers and an operation: addition, subtraction, multiplication or division. The model supplied the architecture and literal weights in a single response, without training the network. The result contains 123 neurons.
Try changing the inputs and selecting different operations. The result comes from evaluating the network’s actual weights, not from asking the language model to perform the calculation.
If you inspect the circuit, much of the arithmetic is familiar. Multiplication works by adding copies of one number, selected according to the bits of the other, with weights of 1, 2, 4, 8 and so on. Division follows binary long division across eight stages: bring down a bit, check whether the divisor fits, and subtract when it does. The network also uses whole-number activations rather than representing everything as individual bits, allowing a more compact construction than one made entirely from Boolean gates.
Because the inputs are limited to eight-bit numbers, we can check the network exhaustively. There are 256 possible values for each input and four operations: 262,144 combinations in total. Every one produces the required result, including the remainder and the division-by-zero flag.
The point isn’t that we’ve discovered a new way to do arithmetic. These are familiar algorithms, expressed using neural-network weights and connections instead of ordinary program instructions. And the model was able to construct that representation correctly for the entire specified domain.
The same computation in two representations
We’ve seen that a neural network can implement arithmetic, and that a language model can generate executable bytes directly. But can it translate between the two?
A compiled program and a neural network can implement the same bounded computation, even though their representations look completely different. Machine instructions tell a processor which operations to perform on its state. The processor ultimately implements those operations using logic circuits. A neural network can implement equivalent operations through its connections and weights.
To test this connection, we gave Astra the bytes of three executables, along with their input/output interfaces. We withheld their source code and function names. The task was to produce neural networks implementing the same behaviour. The networks it generated agreed with the original executables across their complete input domains.
You can select an executable, change its inputs and compare the original program’s output with the corresponding neural network.
The model can express the computation as a network without simulating every processor instruction. For instance, rotating a byte can become a choice of which neurons are connected. A comparison can produce a zero-or-one value that selects between two constants, taking the role of a conditional branch. Even details such as wrapping subtraction and the representation of division by zero survive the translation.
The model recovered an executable’s behaviour and expressed it as a neural network. It’s translation between software representations.
Reading the weights, not just the intention
So far, we’ve looked at generating circuits. But what about understanding what an existing circuit actually does? This is closer to the other side of the MIT experiments: interpreting a network from its weights. Recovering behaviour from an executable is reverse engineering. We can ask the same question about neural-network weights.
We changed one multiplication weight in the earlier calculator from 8 to 9. Ordinarily:
173 × 219 = 37,887
But the relevant bit of 219 is set, so the modified circuit adds one extra copy of 173. Its result becomes:
38,060
We then asked Astra to predict the outputs of both the original and modified networks, given their weights and the input.
The model predicted both results correctly, without execution tools or being told what had changed. Simply recognising that the network implements multiplication would have produced 37,887 in both cases. Getting the modified result requires accounting for what the specific weights actually do.
Of course, reading the weights of a small, deliberately constructed arithmetic network is very different from interpreting a large trained model. In a large network, behaviour can be distributed across many interacting components, making it much harder to understand. But the underlying question is the same: given these operations, connections and parameters, what computation does the network actually implement?
Larger programs need structure
So far, our neural networks have implemented relatively small computations. But how far can we take this? In principle, logic circuits can implement considerably more complex algorithms. The practical difficulty is specifying all the operations and connections correctly.
We explored this using SHA-256, a cryptographic hash function. SHA-256 repeatedly applies operations such as rotations, XOR, selection and addition across 64 rounds. Expressing the entire computation as individual neurons would require a very large, carefully coordinated set of weights and connections. Having the model write every neuron separately would be unwieldy.
Fortunately, conventional software already has an answer to this problem: define a component once and reuse it. We asked Astra to describe a neural network using reusable blocks, their literal weights, and connections between instances of those blocks.
The model produced a network description of roughly 7.4 KB. A generic expander then copied and connected those blocks to produce a network containing 110,594 neurons. The resulting circuit computes the full SHA-256 digest for an input of exactly two bytes.
You can enter two bytes, evaluate the resulting neural network, and inspect its state across all 64 rounds of SHA-256.
The hash itself is computed by weighted sums and ReLUs, using the same evaluator as the earlier calculator. The expander doesn’t implement the hash algorithm; it copies and connects the blocks the model specified.
Nor does this demonstrate that neural networks are a faster way to compute SHA-256. All 110,594 neurons still have to be evaluated, and the implementation only accepts exactly two-byte inputs.
What the experiment shows is that the same principles scale beyond small arithmetic examples, provided we introduce a way to manage the complexity. This is conventional software engineering: reuse components, compose larger computations from smaller ones, and verify that the resulting implementation behaves correctly.
Why might language models be able to do this?
The circuit connection explains why neural-network weights can express these computations. But it doesn’t, by itself, explain why a language model can generate or interpret those weights. For that, we need to consider what language models learn.
Their training material can contain much more than ordinary prose. OpenAI, for example, lists public internet material among its training sources. Software repositories, shared files and datasets contain relationships between descriptions, implementations and results: source code alongside binaries, tests alongside expected outputs, and decoders alongside the formats they interpret.
We don’t know which particular files Astra encountered during training, so this isn’t a claim about the specific source of these capabilities. But such material provides an opportunity for models to learn relationships between different representations of computation.
We already use language models to translate descriptions into source code, or code from one programming language into another. Machine instructions, file formats and neural-network weights are less familiar representations for humans, but they also encode structures and relationships that a model can potentially learn to work with.
What makes these results impressive?
Once we recognise that neural networks can implement logic circuits, the idea of expressing familiar computations through weights becomes less mysterious. But knowing that a particular arrangement of weights must exist is very different from being able to construct it correctly or understand what it does.
That’s what makes these experiments interesting. The model didn’t just recognise familiar algorithms. It generated networks that reproduced arithmetic exactly, recovered computations from compiled executables, and correctly predicted how changing a single weight would alter a network’s behaviour. What connects these examples is the model’s ability to write and interpret representations—from executable bytes to neural-network weights—that are difficult for humans to read directly, yet specify exact computations.
There’s also an important distinction between generating a network and executing it. A language model can make mistakes when producing weights, but once those weights are fixed, the resulting circuit executes deterministically. Just like conventional software, it can be inspected, tested and debugged.
There is, however, a limitation to the networks we’ve explored here. They are fixed directed acyclic graphs (DAGs). They can implement complex computations, including conditional logic, but loops must be unrolled in advance. The SHA-256 network, for example, has all 64 rounds laid out explicitly.
General-purpose computation goes further. With control flow and state, programs can branch, repeat operations and determine what to execute next as they run. With unbounded memory in the theoretical model, this enables Turing-complete computation.
This is also where our work at Blatent takes the idea further. Our models support a Turing-complete programming model during inference, with branching, loops and state, rather than requiring loops to be unrolled in advance into an acyclic, feed-forward network.
Neural networks are circuits. And we’re only beginning to explore what happens when we make their computation programmable.